HIGH-FLYER | AI BLOG

New Releases

FlashAttention: A Novel Attention Algorithm with IO Awareness, Fast and Memory-Efficient

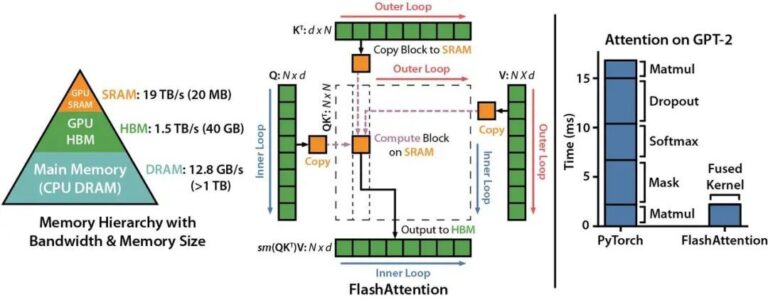
At the heart of the Transformer model is the self-attention mechanism, which has both time and storage complexity at the O(N2)O(N2) level in terms of sequence length. As the scale of large language models (LLMs) continues to grow, equipping LLMs with longer contextual backgrounds poses a significant engineering implementation challenge. A team of researchers from the Department of Computer Science at Stanford University and the State University of New York at Buffalo has published a novel attention algorithm called FlashAttention, which not only has a longer context than PyT
hfai datasets | 运转数据入萤火训练的不二法门

幻方 AI 发布了其沉淀多年的深度学习套件 hfai ,吸引了众多同行研究员和开发者们咨询试用。整个套件的功能较多,而熟悉掌握了这套规则,是能够轻松地调用起平台的算力资源,从而高效完成训练任务的。 为此,我们专门创建了 “hfai 使用心法” 系列专辑,陆续为大家介绍 hfai 一些功能的设计思路和原理,帮助大家更好更快地习得心法,带着 hfai 这套“神功”游刃有余的应对深度学习作业的各项挑战,

hfai images | 自定义镜像,解决环境配置的最后一里路

幻方 AI 发布了其沉淀多年的深度学习套件 hfai ,吸引了众多同行研究员和开发者们咨询试用。整个套件的功能较多,而熟悉掌握了这套规则,是能够轻松地调用起平台的算力资源,从而高效完成训练任务的。为此,我们专门创建了 “hfai 使用心法” 系列专辑,陆续为大家介绍 hfai 一些功能的设计思路和原理,帮助大家更快上手 hfai,游刃有余的应对深度学习作业的各项挑战。 之前的文章为大家介绍了使用 

hfai 心法总章 | 快速上手攻略

幻方 AI 发布了其沉淀多年的深度学习套件 hfai,吸引了众多同行研究员和开发者们咨询试用。整个套件的功能较多,而熟悉掌握了这套规则,是能够轻松地调用起平台的算力资源,从而高效完成训练任务的。为此,我们专门创建了“hfai 使用心法”系列专辑,陆续为大家介绍 hfai 一些功能的设计思路和原理,帮助大家更快上手 hfai,游刃有余得应对深度学习作业的各项挑战。 本终章为大家连贯的演示 hfai

萤火跑模型 | 多卡并行实现 YOLOv5 高性能训练

YOLO 系列模型在整个深度学习目标检测领域有举足轻重的地位,近些年模型性不断发展,工程落地中的应用也十分广泛。 最近来自美国的 Ultralytics 公司发布了第五代 YOLO 模型: YOLOv5。相比上代模型,YOLOv5 以更轻量的参数,更极致的推理速度,一经发布受到了学术界和工业界相关人士的广泛关注。 幻方 AI 最近在萤火集群上对该项工作进行了体验和优化。YOLOv5 没有相应的论文

萤火跑模型 | 能量函数指导的图图翻译扩散模型

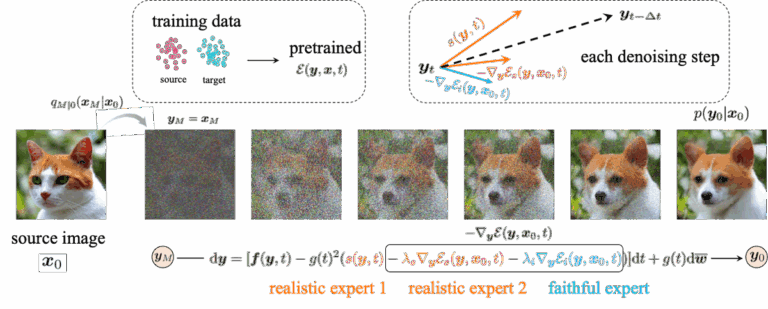
扩散模型作为一种新的深度生成模型,在图像生成领域取得了 SOTA 的效果,并且逐渐在诸多应用领域展现出强大的性能,如视频生成、分子图建模等。 最近来自人民大学李崇轩课题组的研究者们提出了一种基于能量函数的扩散模型生成指导方法 EGSDE。该方法旨在通过预定义的能量函数对预训练好的扩散模型进行指导,从而实现可控生成。现有指导生成方法如 classifier-guidance 等可以理解为 EGSDE

萤火跑模型 | 英伟达元宇宙创造营 GET3D

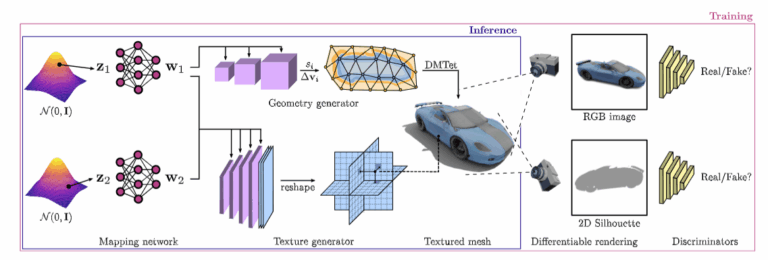
随着多个行业朝着大规模的 3D 虚拟世界发展,能够生成大量的、高质量的、多样的 3D 内容的工具是非常被需要的。英伟达的最新工作 GET3D 希望训练更好的 3D 生成模型,来生成下游任务可以直接使用的、保真纹理和复杂几何细节的 3D 模型。 幻方 AI 最近对这项工作进行了整理和优化,在幻方萤火二号上复现了实验。通过幻方自研的 3FS、hfreduce、算子,对模型训练进行提速,从单机多卡的训练

萤火跑模型 | 分布式训练大规模深度图神经网络

图(Graph)数据在现实世界中非常常见,例如社交网络、交通网络、物理系统等等,近几年图神经网络的发展将图数据的分析与深度神经网络结合,在越来越多的领域发挥出重要的作用,例如电商推荐、生物化学结构分析、反恐反诈风险控制等等。数据规模也呈现越来越大之势,动辄上千万节点规模的图,让很多图神经网络的训练需要探寻并行计算的方式以加速。 然而,图数据与视觉、自然语言等领域的数据不同,没有划分好的训练样本,很

haiscale | Huafang Firefly High-Performance Parallel Training Toolkit

haiscale (Highflyer AI Scale) is a lightweight, high-performance parallel training toolkit that integrates Huafang AI’s years of experience in parallel training research, development, and optimization, enabling PyTorch users to train models on large-scale clusters more efficiently and conveniently. haiscale includes the following tools: haiscale.ddp: a distributed data parallelism tool that uses hfreduce—a communication protocol developed in-house by Huanfang AI—as its backend, offering better multi-GPU scalability compared to NCCL.

haiprof | Model Training Performance Analysis Tool

The entire world is crunching the numbers on GPT’s training and inference costs, to the point where Microsoft couldn’t wait to share the good news that “inference delivers twice the performance per dollar.” The message this conveys is perhaps this: even the slightest waste of computing power can be fatal in this AI race. As this field continues to evolve, the efficiency of model training is increasingly becoming a challenge that researchers cannot afford to ignore. Whether from the perspective of accelerating training to test more parameters or reducing R&D costs, inefficient training has become unacceptable. What researchers need now is a set of user-friendly model performance analysis tools,

GTC 2023 | On-Demand AI Computing Power II

“Don’t miss the defining moment of AI”—this NVIDIA GTC tagline has been trending across the internet since Wednesday. As is customary, the conference featured a series of cutting-edge technology announcements by the familiar face of Jensen Huang, focusing on AI, chips, and other technologies. This year, Huanfang AI was once again invited to deliver a technical presentation at the NVIDIA GTC 2023 conference. Since 2019, to meet the massive computing power demands of our own research work, we have gradually built the Huanfang Firefly Deep Learning Computing Platform, which includes storage, networking, and related infrastructure, as well as time-sharing scheduling.